
How building for frustrated people created the kind of content AI answer engines like to cite
I knew going in that I would never outrank a .gov domain on its own branded searches, so I never tried.
I went after the crumbs instead: the traffic a government site leaves behind because it’s slow, out of date or hard to use. These are people like me who search, land on the official page, don’t find an answer and go looking for someone who’ll explain it in plain English.
I built the site for that person, not for position one. I’d been through the same frustration myself, and I built what I wish I’d found.
What I didn’t plan for was AI answer engines picking up the content the same way. Six months in, AI systems have cited the site more than 490,000 times when answering the exact questions it was built to answer. I didn’t set out to earn AI citations. They came from the same strategy working better than I expected.
The reality check
Before I wrote a single page, I accepted three things:
- I was never going to outrank the department’s own .gov domain on its branded searches. Nobody does.
- AI Overviews and other AI answer engines would struggle with these questions, because the source material on government sites is thin, out of date or badly structured.
- That gap meant there would always be space left in the search results. I’d never take the top spot, but I could win the people who bounce off the .gov result and want a plain-English explanation, a checklist or a tool the government site doesn’t offer.
The plan was to build something that could sit in that gap for good, and that I wouldn’t need to babysit around my schedule.
What I built
- I registered a domain and built a custom, text-only theme so the site would load fast. The topic didn’t need pictures or videos.
- I made a topical map covering almost every question I could find, from my own experience, conversations with government officials, forums and search data. I organised it around the main documents and applications people in this niche need.
- I built free tools people needed: a process finder, a checklist generator and a complaint letter generator.
- I stated clearly on every relevant page that the site isn’t affiliated with any government department, and showed the date each page was last updated.
- I wrote for readers like me, who had already tried the official channels and found they weren’t working.
The results after six months
Bing search performance
The site got 32.8K clicks and 814.5K impressions at an average CTR of 4.03%. The graph shows the real story. An early spike in March had faded by April. Then came four months of almost flat traffic, followed by a steady climb from late June that kept building through August, peaking at around 800 to 900 clicks and 20,000 to 25,000 impressions on the best days.
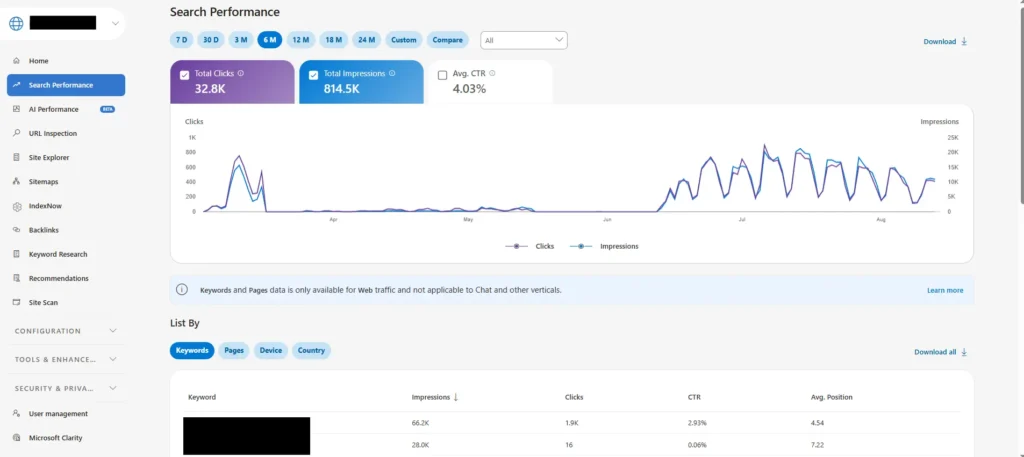
The top queries are exactly the crumbs I was hoping for. The biggest single query, a branded “online booking” search for the department, brought 66.2K impressions and 1.9K clicks at an average position of 4.5. Nobody gets that position without content that answers the question. A close variant with the same booking intent converted at 2.70% CTR from position 4.24, and a shorter version of the query reached 3.87% CTR. These are searches from people ready to act, and the site is winning them from a non-official position.
Google Search Console tells a different story
Over the same six months, Google sent 13.2K clicks from 747K impressions, with an average CTR of 1.8% and an average position of 9.7. The traffic pattern differs from Bing too. There’s a similar early spike, a sharp peak in mid to late April and a taller one in mid-May. But instead of Bing’s steady climb from June to August, Google traffic dropped hard after mid-May and settled into a much lower, flatter band, with only a small rise heading into August.
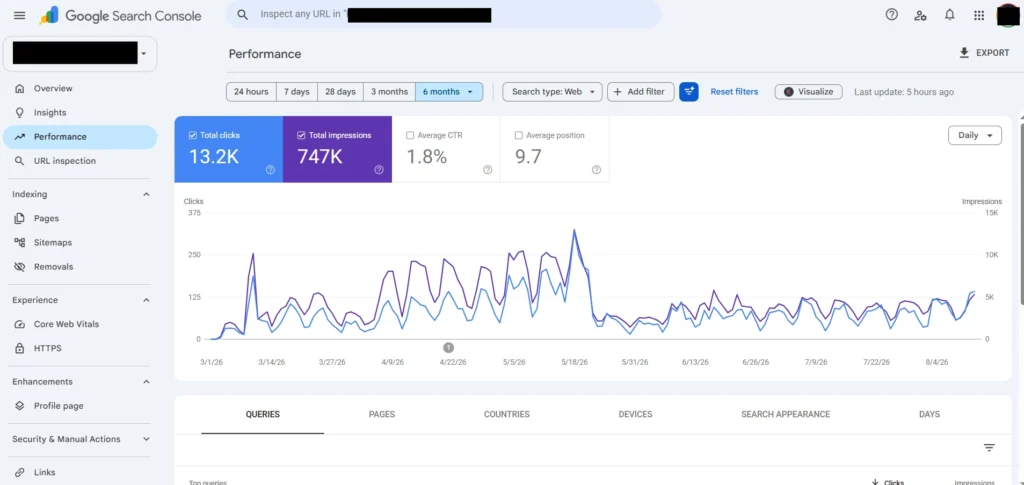
The gap between the two engines is the more interesting finding. On Bing, the site lands around position 4 to 5 on its best commercial searches. On Google, the average across all queries is 9.7, which is the bottom of page one, and CTR is less than half of Bing’s. It’s the same content on the same site over the same six months, with very different outcomes. Ranking well depends on the engine, and a site can do well on one while still fighting for a foothold on the one with the biggest market share.
Google Analytics
Since January the site has had 49.2K active users and 308K events. The shape matches the Bing data: a spike, a long flat stretch, then a real climb from June onward that is still going.
Engagement in Microsoft Clarity
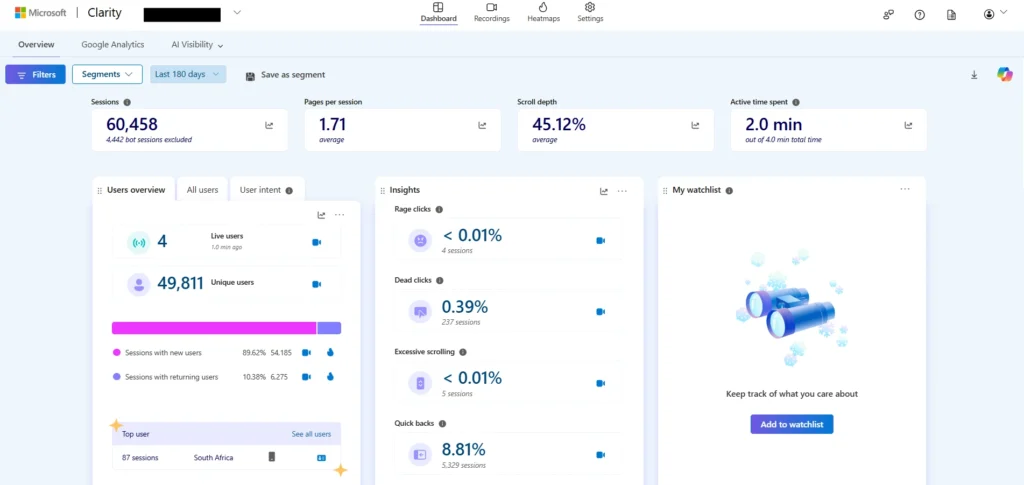
Clarity recorded 60,458 sessions over 180 days, with bot sessions already excluded. Visitors viewed 1.71 pages per session, scrolled an average of 45% of each page and spent 2 minutes actively engaged out of 4 minutes on the site. For a utility site people visit to solve one specific problem, that means they’re reading.
What I didn’t expect: AI citations
This is the number that confirms the original idea. Bing’s AI Performance report shows more than 500K total citations over six months, with an average of 42 pages cited. It follows the same growth curve as the click data, flat until late June and then climbing steadily through July and August 2026.
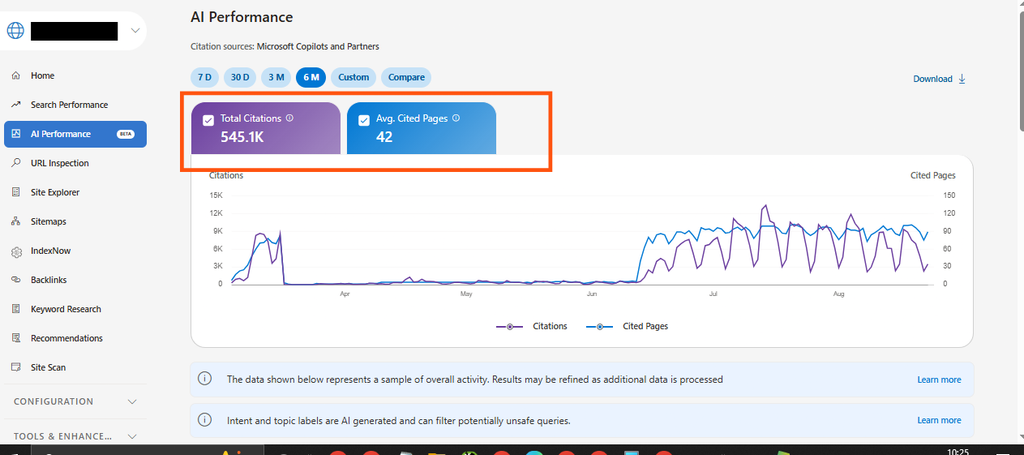
The grounding queries behind those citations match how people search almost exactly. The largest share came from a core identity-document query, where people want information. Close behind was the same branded booking query that leads organic clicks, where people want to act. Then came an application-status query, where people want a tool, followed by a specific document-type query, a document-format query and a few renewal and status queries further down.
This confirms the second part of the bet. The same gap that created the search opportunity is making this content useful to AI answer engines. The official source has the authority, but the third-party page is easier to find, understand and use.
Where the traffic comes from
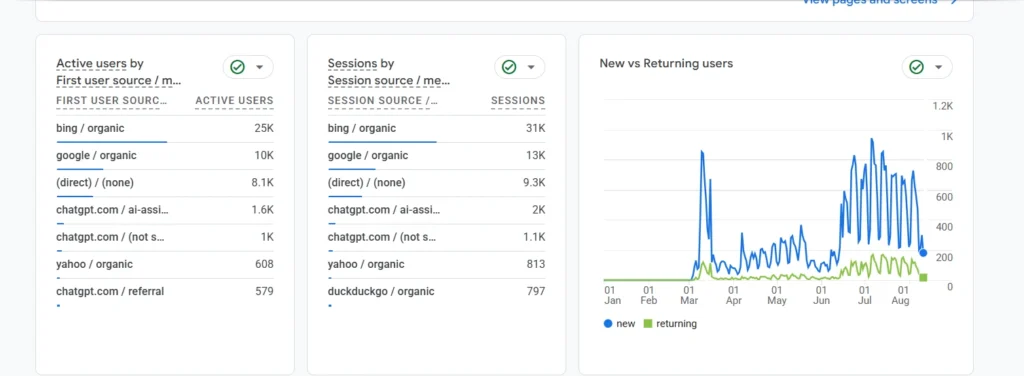
By first-touch source, Bing organic leads by a wide margin with 25K active users. Google organic brought 10K and direct traffic 8.1K. Yahoo and DuckDuckGo added a few hundred each.
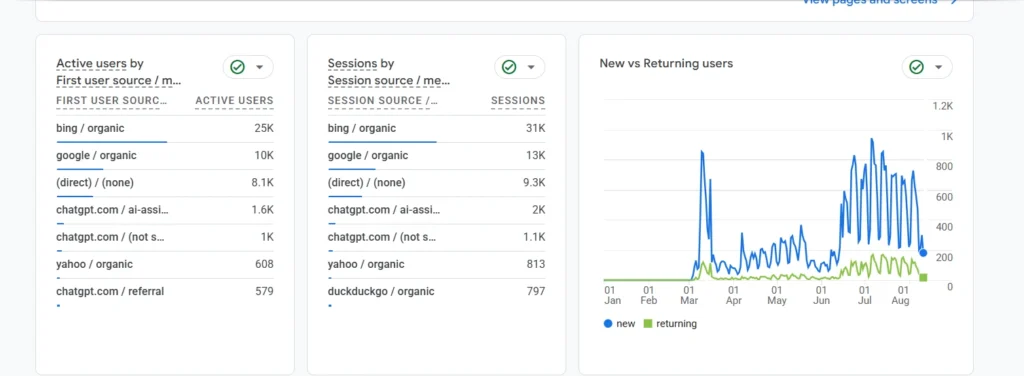
ChatGPT stands out. Across its “ai-assisted”, “not set” and referral attribution, ChatGPT sent roughly 3.2K active users and 4.1K sessions. That’s a fourth real acquisition channel, one that barely existed a couple of years ago, and it’s already ahead of Yahoo and DuckDuckGo combined. Sessions follow the same pattern: 31K from Bing organic, 13K from Google organic, 9.3K direct and roughly 3.1K from ChatGPT sources.
The new versus returning users chart has the same shape as every other graph here. It’s flat, spikes in March, fades, stays flat, then climbs steadily from late June through August, mostly with new users. Returning users grow too, slowly and steadily, which is what you’d expect from a site people visit once to solve a specific problem.
Taken together, the Bing citation data and the ChatGPT referrals show that AI systems are surfacing and citing this content alongside traditional search, and that channel is growing at the same rate as everything else.
Why this worked
There’s no trick here. It’s the basics, applied to a category most people ignore because it looks dull and nobody wants to do the hard work.
- Topical depth beats domain authority when the incumbent’s content is poor. A .gov domain wins on trust but loses on usability, and structured, current, plain-language content fills that gap.
- Tools outperform articles for this kind of search. A checklist or complaint letter generator solves the problem on the spot, which is why pages per session, scroll depth and time on site are healthy.
- Saying clearly that the site isn’t affiliated with the government didn’t hurt trust. It probably helped, because this audience is already wary of anything that looks official and isn’t.
- The flat months mattered. During four months of almost no traffic before the June climb, indexing, crawl trust and topical authority were building up before they showed in the numbers.
Someone who read an early draft of this put it better than I could:
“You found a structural inefficiency in how public information is delivered, fixed the user interface, and let search engines and AI parsers do the distribution for you. It’s a rare case of doing SEO by simply delivering better utility. This is a textbook execution of ‘gap arbitrage’ in SEO and Information Retrieval. You identified an asymmetry between Domain Authority and Information Architecture, and exploited it. High-DA sites (.gov, .edu, legacy media) routinely rank on trust, but suffer from high bounce rates when their user experience is friction-heavy, dense, or broken.”
The gap arbitrage framework
Official authority → poor information experience → unresolved user intent → third-party utility layer → search visibility → AI retrieval and citation.
That’s the framework I found, and I think it applies well beyond government websites.
The human part
I built the website to help people, and every so often I get an email from someone who found it useful.
Lessons
1. Usability beats domain authority in the long tail
High-authority sites like .gov domains, legacy media and big corporations get early ranking trust, but a poor user experience sends visitors back to the results. You don’t need position one to build a big audience. Winning the crumbs at positions 4 to 9, from people bouncing off dense, broken or outdated pages, brings in traffic that wants to act.
2. Search engines diverge
Ranking well means different things on different engines, because each one weighs entity trust and on-page usefulness differently. Bing may reward a usable, well-matched utility page with position 4, while Google holds the line on YMYL and entity trust at position 9. Know which engine you’re optimising for.
What’s next?
Nothing, apart from updating the site whenever the official rules change.